Register a cluster
Registering a cluster gives kubelatch two ServiceAccounts on it: one to act as the proxy and one to keep RBAC in sync. When it's done, the cluster shows up as Ready in Clusters and you can start granting permissions on it.
Before you start
- A kubelatch administrator (Install).
- An administrator kubeconfig for the cluster you're registering, or a cluster that trusts kubelatch's OIDC client, to enroll it with your identity.
- Network: kubelatch's pods must reach the API server over https. If it's private, see Private clusters.
- Kubernetes 1.30 or later on the cluster: the bootstrap manifest carries a
ValidatingAdmissionPolicy, and validation usesSelfSubjectReview.
flowchart LR
  A["Register a cluster" in Clusters] --> B[Generate the enrollment command]
  B --> C[Run it with the cluster's kubeconfig]
  C --> D[kubelatch validates and encrypts]
  D --> E[First reconciliation]
Register the cluster
The Free edition allows 2 clusters; the 3rd registration answers 422 edition.limit. At the limit, Clusters says so in a note, and Register in the panel says why it cannot. See Editions and license.
-
In Clusters, click Register a cluster. A panel opens on the right: fill in Identifier (slug, goes in the proxy URL) and Name and click Register. The identifier is a slug (lowercase letters, digits and dashes, up to 63 characters) and goes in the proxy's URL:
https://<kubelatch>/clusters/<id>. You land on the cluster's own page, with the status Not enrolled, at its Enroll card. The card shows the steps while the cluster is not enrolled; to come back to it, open the cluster from Clusters, or choose Enroll in the menu of its card or row. -
With OIDC login on, the card first asks How: With my identity (Keycloak), under your provider's name (Enroll with your identity), or With the script, which these steps follow. The script has three numbered steps. In the first, Where, type in kubectl context (optional) the context of your kubeconfig that points at that cluster, or leave it empty to use the current one. The command carries it as
sh -s -- --context '<name>', and you can still change it once the command is out. If this is the cluster kubelatch itself runs in, check kubelatch runs inside this cluster (useskubernetes.default.svc). Click Generate command.Most clusters need nothing else: kubelatch takes the API server address from the
serverof that context. If kubelatch reaches the API server at another address (a private network, an internal DNS name), open Advanced options and type it in API server URL for kubelatch (Private clusters). With the checkbox checked, that field is locked tohttps://kubernetes.default.svc, the address a pod uses. -
In the second step, Command, copy the Enrollment command and run it with that cluster's administrator kubeconfig. It's a
curl … | shthat uses the context from the first step, orkubectl's current one. With the kubeconfig in another file, pin it in a subshell:(export KUBECONFIG=<cluster-kubeconfig>; <enrollment-command>) -
The script prints the kubectl context and API server it will enroll, and asks
Continue? [y/N]on your terminal. Check that they are that cluster's before you answery: the manifest goes to whatever cluster the context points at, and the Check the context before you confirm note under the command says so. It then applies the bootstrap manifest, waits up to a minute for Kubernetes to fill in the tokens and sends them to kubelatch.
The third step, Waiting, follows the command while it is pending (Waiting for the command to run…). If an attempt reaches kubelatch and fails, it shows the last one with its reason (Last failed attempt at …). When kubelatch receives the tokens, validates them and stores them encrypted, the card says Enrolled. First reconciliation under way., the steps give way to the page's tabs and the header says how the cluster is doing. The tokens are never shown again.
The link is a secret that works once and for one hour: the card shows when it expires (Single use · expires at …). Don't paste it in chats or tickets. The command shows only in the tab that generated it: come back to the page, or open it as another administrator, while the link is pending and the card says Pending link · valid until …, without the command, and offers Generate another command. Invalidate cancels the link before it's used (the copied command stops working), and generating a new command replaces the previous one. The link also stops working if the administrator who generated it is disabled or loses the admin role. If the link expires or is invalidated, the card says so and offers Generate a new command.
Generating or invalidating a command and receiving the tokens leave events in the control plane (cluster.enrollment.create, cluster.enrollment.revoke and cluster.tokens with via: enrollment): see Audit.
Enroll with your identity
With OIDC login on, you can enroll a cluster by signing in to your identity provider instead of running a command: kubelatch applies the bootstrap manifest itself with the ID token the provider gives you, stores the two ServiceAccounts' tokens encrypted and discards yours. No terminal, no kubeconfig. It works the same in the Free and Pro editions.
When it works
The cluster's API server must accept the ID token kubelatch receives at sign-in: it trusts the same issuer with kubelatch's client ID (OIDC_CLIENT_ID) as audience, and maps the token's claims to your user and groups (the e-mail and, if you're an administrator through a group, groups). A public and a confidential client work alike: what counts is the token's audience. If your provider includes the groups only with a scope, add it to OIDC_SCOPES.
| Cluster | How it trusts kubelatch's client |
|---|---|
| kubeadm, k3s, Talos, RKE2 | --oidc-issuer-url and --oidc-client-id with kubelatch's client ID, or an AuthenticationConfiguration with that audience |
| DOKS | Its single sign-on, with kubelatch's public client |
| EKS | An OIDC identity provider associated with the cluster, with kubelatch's client ID |
| EKS with IAM Identity Center alone | It accepts no OIDC token: use the script |
| AKS | Its tokens' audience is AKS's own server application: use the script |
| GKE | It asks for a Google access token: use the script |
A cluster without SSO, or one that trusts another provider, keeps the script: its API server refuses the token. kubelatch can't know what a cluster trusts before you sign in, so the choice says it, naming the client (Only if the cluster already trusts Keycloak with kubelatch's client kubelatch; otherwise, use the script.), and a refusal says it again.
The identity has to be yours: the one your account has linked to the provider (How accounts are linked), so the cluster's audit log and kubelatch's name the same person. Without one, the choice is disabled with Your account is not linked to Keycloak. Link it in My account. A break-glass account, never linked, reads Your account is a break-glass one, with no Keycloak identity: use the script.
Configure the cluster
Whatever the provider, the name the API server gives you needs the rights to apply the manifest, which cluster-admin has: a ClusterRoleBinding for your user or one of your groups, as the cluster names them.
-
kubeadm, k3s, Talos, RKE2: start the API server with
--oidc-issuer-urlset to your provider's issuer (OIDC_ISSUER),--oidc-client-idset to kubelatch'sOIDC_CLIENT_IDand the claim flags of Cluster SSO by provider; on k3s, through--kube-apiserver-arg. Or give it anAuthenticationConfiguration(--authentication-config), which it reloads without a restart and which takes several audiences, so the cluster can trust kubelatch's client beside its own (audienceMatchPolicy: MatchAny):apiVersion: apiserver.config.k8s.io/v1 # v1beta1 before Kubernetes 1.34 kind: AuthenticationConfiguration jwt: - issuer: url: https://auth.example.com/realms/acme # OIDC_ISSUER audiences: - kubelatch # OIDC_CLIENT_ID claimMappings: username: claim: email prefix: "oidc:" groups: claim: groups prefix: "oidc:" -
DOKS: set your provider's issuer and kubelatch's client ID in the cluster's single sign-on. DOKS asks for a public client (Public or confidential client).
- EKS: associate an OIDC identity provider with the cluster, with your provider's issuer, kubelatch's
OIDC_CLIENT_IDas the client ID, and the username and groups claims with their prefixes (Cluster SSO by provider). - AKS and GKE: use the script.
The cluster takes your user from a claim of the ID token: email in the example. A provider that leaves the e-mail out of the ID token, such as Entra ID without its optional email claim, gets a 401 even with the issuer and the audience right: map a claim the token carries, or add the e-mail to it. With email, the API server also refuses a token whose email_verified is false.
The cluster kubelatch runs in
The form asks Where is the cluster? For this one, choose kubelatch runs inside this cluster. kubelatch reaches it at https://kubernetes.default.svc and verifies it with the CA Kubernetes publishes in every namespace, in the kube-root-ca.crt ConfigMap, which the chart mounts read-only (What the chart installs). The form says kubelatch already knows the address and the CA of this cluster. and asks for nothing. Without the mount (an older chart, clusterCA.mount: false, kubelatch outside Kubernetes) it says kubelatch does not have the CA of this cluster: paste it. and asks for the CA alone. If the mounted CA doesn't sign the API server's certificate (because it has a serving certificate of its own), open Paste the CA by hand and paste the right one: after that failure, the panel opens it by itself. The command output pasted there fills in the CA alone: kubelatch keeps the address it has inside the cluster.
Another cluster
Choose Another cluster and fill in API server URL and API server CA: from the provider's console, when it shows them (EKS shows both on the cluster's page), or with the Read-only command, which prints only those two values and doesn't talk to the cluster:
kubectl config view --minify --raw --flatten -o jsonpath='{.clusters[0].cluster.server}{"\n"}{.clusters[0].cluster.certificate-authority-data}'
Fill in kubectl context (optional) and the command reads that context instead of the current one. Paste its two lines in Command output, beside the note that kubelatch doesn't need your kubeconfig. Under What kubelatch will use the panel lists the URL and the CA, with how many certificates the CA holds and the SHA-256 fingerprint of each: compare it with the one your provider shows, or with openssl x509 -noout -fingerprint -sha256. The fields fold under Type the URL and the CA by hand; open it to type or paste them yourself: the URL passes the same checks as the script's (What kubelatch validates), and the CA takes PEM or base64.
Two warnings never block: an address that is already another registered cluster's (This address is already that of cluster "prod": check that it is the cluster you mean to enroll.), and a loopback address, which kubelatch opens from its own server, so it only works when the API server runs on that same machine.
Sign in at the provider
Under the fields, Before you go lists what will happen before you leave: You sign in as ana@acme.com at Keycloak; Applied at https://10.0.1.10:6443 · cluster "prod"; What the manifest creates, with View the manifest, which shows the manifest itself in place; and Your token: It is used only for this and is not stored. Click Continue to Keycloak: kubelatch asks the provider to propose that identity, and that's the one to sign in with.
While you're at the provider, the panel says Waiting for you to come back from Keycloak · expires at 10:42, with Cancel: the sign-in has 10 minutes. When you come back, kubelatch does the work in that same request, usually in seconds and in two minutes at most, and you land on the cluster's page with Enrolled with your identity. The API server saw you as oidc:ana@acme.com (groups oidc:platform-admins). Reconciliation under way. While kubelatch applies the manifest (kubelatch is applying the manifest…), neither Cancel nor a new enrollment stops it, so the cluster is never left half enrolled. Another administrator who opens the cluster meanwhile reads the run under your login, never your address (Waiting for "ana" to come back from Keycloak · expires at 10:42), and their Cancel asks first (Cancel the enrollment of "ana"?): you may be signing in right then.
Re-enroll and Re-enroll without changing the tokens offer the same two ways, and the panel says which from the start: its title (Re-enroll "prod" with new tokens, Re-enroll "prod" without changing the tokens) and the sentence under the way (With your identity, kubelatch applies the manifest again and stores new tokens: the current ones stop working.). Where is the cluster? starts on Where it already is, with the registered address: kubelatch uses the address and the CA it already has for the cluster, and there's nothing to paste. If another administrator changes that address while your page is open, kubelatch refuses to continue and the panel reads the cluster again, so the token goes only where the page said. Choose another place only to change them. With new tokens, Before you go adds kubelatch's current tokens in the cluster are replaced., and the page then says Re-enrolled with your identity, with new tokens. As with the script, applying the manifest again leaves kubelatch-proxy with the uids-only rule; kubelatch reconciles the cluster as soon as it has written to it, so that lasts seconds.
What kubelatch does with your token
- It sends it only to that URL, over TLS verified against that CA alone, and follows no redirect. A certificate the CA doesn't sign stops everything before the token leaves.
- It asks the API server who you are (
SelfSubjectReview) and which version it runs, and checks withSelfSubjectAccessReviewthat you may create everything in the manifest, before writing anything. - It applies the bootstrap manifest, the same one the script applies, object by object by server-side apply, then waits up to a minute for the two token Secrets and reads them.
- From then on it uses only the ServiceAccounts' tokens: it validates them as it validates the script's and stores them encrypted. Your token never reaches the database, an event, a log line or a response: it lives only in the request that brings you back from the provider.
The control plane records cluster.bootstrap, with your verified identity and who the API server saw you as, and cluster.tokens with via: identity (Audit).
kubelatch never asks for your kubeconfig
kubelatch never asks for your kubeconfig, on this screen or any other: what it needs, the API server's URL and CA, isn't secret. An administrator kubeconfig (k3s's and kubeadm's carry cluster-admin's certificate and key) is the most sensitive credential you have at hand, and on a web page any browser extension with access to it could read it. The note beside the fields says so: kubelatch does not need your kubeconfig.
If you paste a kubeconfig or a credential anyway, the field is wiped at once and the page says That looks like a whole kubeconfig. kubelatch neither needs nor reads it: use the command, which prints only the URL and the CA. Nothing is sent, but the text was on the page for an instant: treat that credential as exposed to the browser's extensions. The defences against extensions are in Security model.
When it fails
The panel says The enrollment with your identity did not finish and when, why, what the attempt left in the cluster and, when it got that far, who the API server saw you as, in mono. The first button fixes the cause: Use the script when the API server refused the token or your identity lacks a right; Correct the CA when the CA doesn't sign the API server's certificate, which brings the form back with the URL and an empty CA, focused; Try again otherwise, with the same URL and CA. What this failure means opens its row in Troubleshooting. If another administrator opens the cluster, they see the attempt under your login (The enrollment with the identity of "ana" did not finish), without your address, and their Try again starts from an empty form: your URL and CA are never theirs to send a token to. Without an identity linked to your account, Try again waits and says where to link it.
kubelatch writes nothing to the cluster when the API server refuses the token, when its certificate isn't signed by the CA (the token isn't even sent), when the cluster runs Kubernetes older than 1.30, or when the identity the API server sees lacks a right the manifest needs, which the message names. An object refused while applying is named with the API server's answer; what was applied stays, as with the script, and trying again is idempotent. Tokens that don't show up within a minute, or don't validate, aren't stored, and the manifest stays applied. A re-enrollment with new tokens deletes the old ones before it applies, so when it fails past the checks the panel adds As it asked for new tokens, the previous ones may already be deleted: kubelatch cannot reach the cluster until an enrollment finishes.: the proxy and the reconciler stay out until one does. A sign-in that doesn't finish (cancelled at the provider, another identity) says why as the login does (When a sign-in fails). Every message and its fix: Troubleshooting.
Script options
Pass them after sh -s --, for example curl … | sh -s -- --yes:
| Option | What it does |
|---|---|
--context <name> |
Uses that kubectl context instead of the current one. |
--server <url> |
The API server address kubelatch will use. Wins over the one set in the card; without either, the script takes the server of the kubeconfig. |
--rotate |
Deletes the two token Secrets before applying the manifest, so Kubernetes issues new ones. The card bakes it in for Re-enroll, which asks for new tokens (Rotate the ServiceAccount tokens). |
--yes |
Skips the confirmation. Without it, the script asks on the terminal (/dev/tty) and, with no terminal (CI, a pipe with no tty), stops with no terminal to confirm on: rerun with --yes. |
The script needs kubectl, curl and base64 in the PATH, and curl 7.76 or later. The tokens travel to kubelatch in the body of a POST sent through stdin: they never show up in a process's arguments. If kubelatch uses a certificate from a private CA, point curl at it for both steps, the download and the POST: CURL_CA_BUNDLE=/path/ca.crt, set in the subshell with KUBECONFIG.
If kubelatch refuses the tokens (for example because it can't reach the API server), the script says so, the card shows the attempt and its reason, and the link stays valid until it expires, is used or is refused 10 times: rerun it, with --server if needed.
Do it by hand
The same registration step by step, if you can't run the command (for example because the cluster's shell has no curl). Under Do it by hand, at the foot of the card:
-
Download the manifest (download bootstrap.yaml) and apply it with that cluster's administrator kubeconfig:
kubectl --kubeconfig <cluster-kubeconfig> apply -f kubelatch-bootstrap-<id>.yamlIt creates the
kubelatch-systemnamespace, thekubelatch-proxyandkubelatch-reconcilerServiceAccounts each with a token Secret, thekubelatch-proxyandkubelatch-reconcilerClusterRoles and their two ClusterRoleBindings, and thekubelatch-reconciler-jailadmission policy with its binding, which bounds what the reconciler may write (Security model). On a cluster older than 1.30,kubectl applyfails on that policy's kind. -
Copy the One-liner and run it with the same kubeconfig. It uses
kubectl's current context, so pin it in a subshell:(export KUBECONFIG=<cluster-kubeconfig>; <one-liner>)It waits up to a minute for Kubernetes to fill in the tokens and prints a JSON with
server,ca,proxyTokenandreconcilerToken. It reads the CA with--flatten, so a kubeconfig withcertificate-authority: <file>works too. -
Paste the JSON into Tokens JSON and click Save tokens.
kubelatch validates the tokens against the cluster, stores them encrypted and kicks off the first reconciliation; the card says Tokens saved. Reconciliation under way.
What kubelatch validates
- The API server URL:
httpsonly, no user, query or fragment, and never a literal link-local, metadata or multicast IP (names aren't resolved to check this). - The CA: the base64 PEM (
certificate-authority-data) or the raw PEM. - Each token's identity with
SelfSubjectReview:proxyTokenmust bekubelatch-proxyandreconcilerToken,kubelatch-reconciler. - Each ServiceAccount's permissions with
SelfSubjectAccessReview: the proxy must be able to impersonateuids; the reconciler, read RBAC objects, write ClusterRoles and bindings,bindeach tier's roles, list namespaces and createSubjectAccessReviews. Both the current manifest and the previous one pass: the reconciliation finds out which one the cluster has (Update the bootstrap).
If something fails, the 400 says what: proxyToken: the token belongs to …, the ServiceAccount kubelatch-reconciler lacks the permission …: apply the bootstrap manifest again. More cases in Troubleshooting.
Check that it works
- In Clusters, the cluster's card says Ready, and the Last pass column of the List how long ago it was reconciled (
reconciled 3 min ago). Until the first pass ends it saysfirst reconciliation under way: reload the page if it takes more than a few seconds. - On the cluster's page, Details, on the Status tab, gives the Kubernetes version, the Provider (
Amazon EKS,K3s,Kubernetes…; how it is worked out) and the Bootstrap (v2), and Namespaces, on the Access tab, lists the namespaces with their PSA level (PSA restricted,no PSA…). -
The cluster shows the ClusterRoles for each tier:
kubectl --kubeconfig <cluster-kubeconfig> get clusterroles -l app.kubernetes.io/managed-by=kubelatch
The Clusters screen
Clusters opens with a sentence of figures: how many clusters there are and in how many providers, how many need attention, how many have warnings and how many are not enrolled (12 clusters in 3 providers · 1 needs attention · 2 with warnings), or all ready. Under it come Needs attention, when something does, and two tabs with the same clusters: Diagram and List. A phone opens the List, and the Diagram is one tab away. The view stays in the address (?view=list). Beside the tabs, Environment and Label narrow both views to the clusters of one environment or with one label (Environments and labels).
Needs attention
Each cluster has a level, the worst of what it says, and the card lists what needs attention in this order:
| Level | Pill | When | Link |
|---|---|---|---|
| 1 · Security | Blocked | A privileged name breaks the 8-hour rule, or a role a namespace takes away leaves people without the whole cluster. The line says how many people are left without access, and why. | How to fix it, to Needs attention on the cluster's page. |
| 1 · Security | Exposed | The cluster gives privileged access to everyone it authenticates. | How to fix it. |
| 2 · kubelatch can't work | Unreachable or Token rejected | kubelatch can't reach the cluster's API server, or the server refuses the reconciler's token. The line says when the last pass that worked was. | How to fix it. |
| 2 · kubelatch can't work | Overdue | No pass has ended on the cluster for 30 minutes, three times the period of the reconciliation. | How to fix it. |
| 2 · kubelatch can't work | Error | Any other problem of a cluster in error: the line says the first one. | How to fix it. |
| 3 · Warnings | Warning | Bootstrap v1, a Kubernetes version out of support, accounts that can't be named, or a role without effect in a namespace that leaves nobody out. They all go in one line. | View, to the List with with warnings pressed. |
Levels 1 and 2 take one line per cluster, five at most; and N more opens the List with need attention pressed. A cluster that is not enrolled is no incident and never shows here. With nothing to say, the card is not drawn.
The diagram
The diagram draws kubelatch at the top, with how people sign in (Sign-in with Google and GitHub), and under it the clusters in boxes. Group by, beside the tabs, chooses the boxes: per Provider, per Environment or per value of a label key (Group the diagram). It opens on Environment once a cluster has one, and on Provider otherwise. Per provider, the boxes are AWS, Google Cloud, Azure, DigitalOcean, Scaleway, OVHcloud, Exoscale, Aruba, Red Hat, Own and edge (K3s, RKE2, kind, Talos Linux, generic Kubernetes and any other) and Not enrolled. They keep that order, in as many columns as the screen holds, and an empty one is not drawn. Each box holds its clusters, the worst first, as cards: the provider's mark and the identifier, and under them the pill of its level (Ready, Warning, Error…), the product and the Kubernetes version (EKS · 1.32), with bootstrap v1 when it is. The line that leads to a box holding a cluster of level 1 or 2 is red.
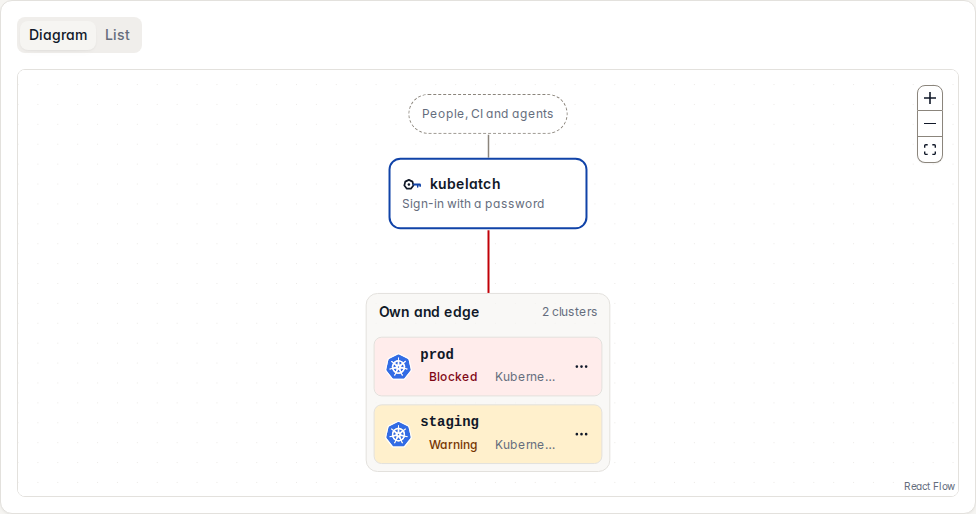
Click a card to open the cluster's page; its menu has Enroll (until it is enrolled) or Reconcile, and Delete. A box with more than six clusters keeps a card for each one with something to say and gathers the others in N ready, one chip per cluster that opens its page. The mouse wheel scrolls the page: zoom with the buttons at the top right, and drag the canvas to move it. With the keyboard, Tab goes through the cards box by box, each card and then its menu.
The list
The List says the same in a table, the worst first: the cluster with its name under it, the pill of its level, the provider, the Kubernetes version (with out of support when it is), the bootstrap, the last pass (reconciled 3 min ago, last failed 2 h ago), and three figures that link to the lists they count: accounts, permissions and credentials restricted to it. The search looks in the identifier and the name, and the chips need attention, with warnings and not enrolled, each with its count, narrow the list and stay in the address. On a phone each cluster is a row.
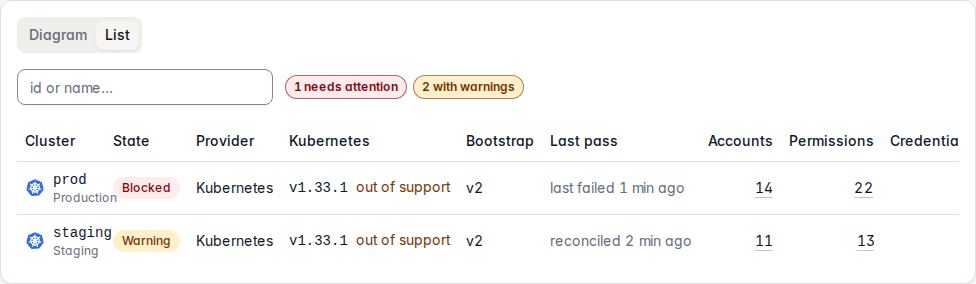
The provider marks follow the KUBELATCH_PROVIDER_LOGOS setting: published by default, all or none. The provider's name is always shown in text.
The cluster's page
Click a card in the diagram, or a cluster in the List, to open the cluster's own page, /admin/clusters/<id>. The header says what the cluster is and how it's doing, with the same word as its card in Clusters: the provider's mark and the identifier, the name, the pill of its level (Ready, Warning, Blocked…), its environment (prod · Production for one marked as production, the id alone otherwise), the product and the Kubernetes version (Amazon EKS · 1.33, with out of support when it is), and the last pass: reconciled 3 min ago; last good pass at 10:05 (1 h ago) while the cluster is blocked or kubelatch can't work on it; last pass 2 h ago when it's Overdue. Under it go the cluster's labels and Environment and labels, which changes both (A cluster's environment and labels). Reconcile and, in the menu (the three-dots button), Re-enroll and Re-enroll without changing the tokens appear once the cluster is enrolled; Delete is always there.
Under the header come three tabs. The page always opens on Status, and the tab stays in the address (?tab=access, ?tab=inside):
- Status:
- Needs attention, when the cluster has something to say (below).
- Four figures: Locked out (the people a problem leaves without the cluster), Expire today, No expiry and Active credentials for this cluster.
- Recent activity, in two parts. Changes lists the last 10 changes of the control plane on this cluster, its own and those of its permissions: who granted what, and when. Requests lists the last 20 requests, each opening its detail. Open in Audit lists the rest, filtered by this cluster.
- Details: API, Kubernetes version, Provider, Bootstrap, Registered, Proxy path and Kubeconfig context.
- Access:
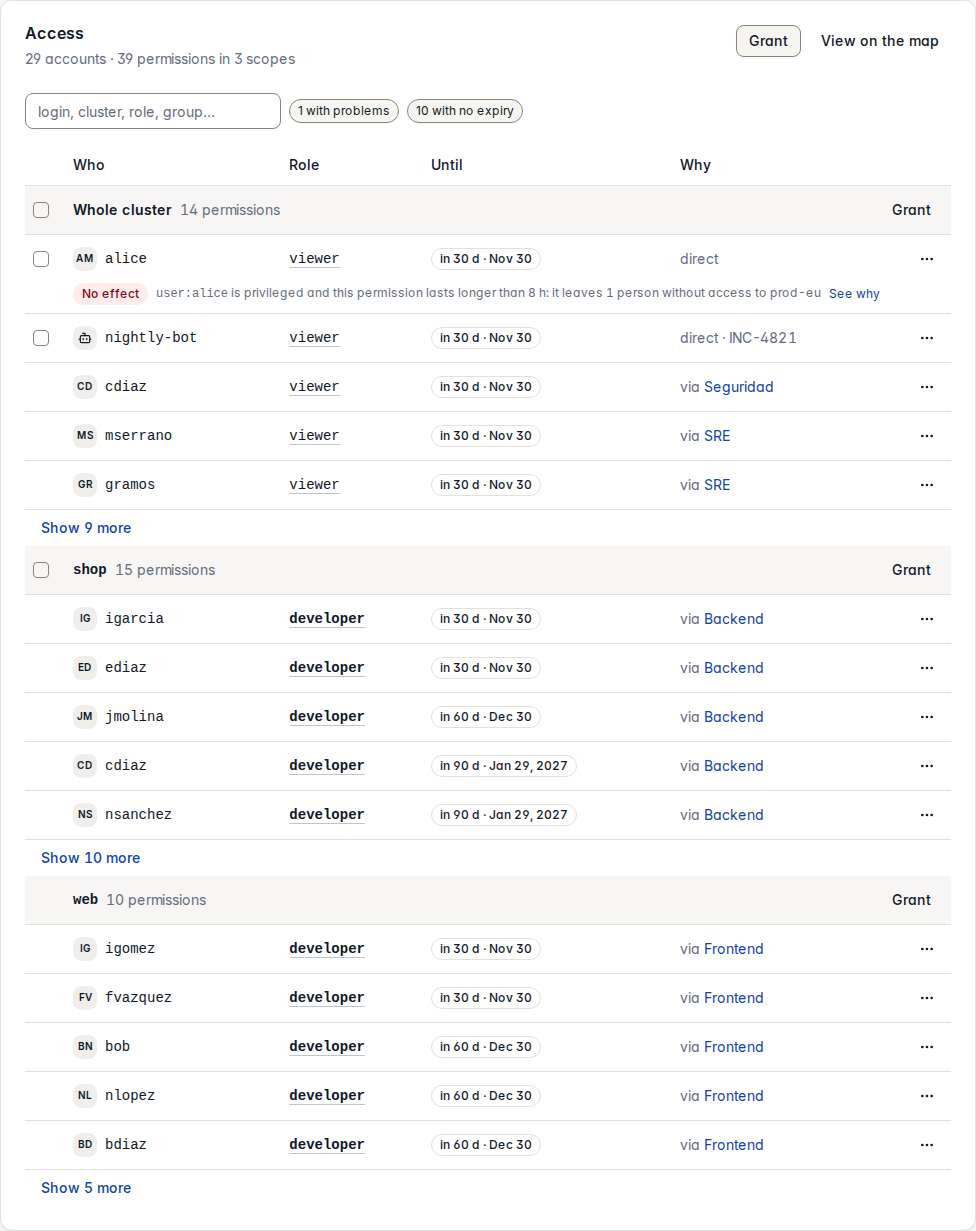
- Access: the active permissions, grouped by namespace (the whole cluster first), one line each with the account, the role, the expiry and whether it's direct or through a group (Read a permission). A sentence counts them (
29 accounts · 39 permissions in 3 scopes). The search finds an account by its login, its name, the role, the namespace, the note or its groups, and the chips of Permissions narrow the lines: expire today, this week, with problems, with no expiry and cluster-admin; Clear removes both. A namespace with more than 8 permissions shows 5 and Show N more. What keeps a permission from working shows under its line, and a disabled account's are dimmed. Grant opens the permission form of Permissions with the cluster, and beside a namespace that namespace, filled in; See in Permissions opens Permissions on this cluster. - Namespaces: a filter by name and, for each namespace, its PSA level, the permissions in force and Grant. A protected namespace says Protected instead. Tick several and choose Grant in N namespaces in the bar to open the form with all of them.
- Access: the active permissions, grouped by namespace (the whole cluster first), one line each with the account, the role, the expiry and whether it's direct or through a group (Read a permission). A sentence counts them (
- Inside the cluster:
A cluster that is not enrolled has no tabs: under its header come the Enroll card, the permissions granted so far, which reach the cluster once it's enrolled, and Details. A re-enrollment opens its card above the tabs, and it stays there whichever tab you open until the command runs or you cancel it.
The cluster's Needs attention
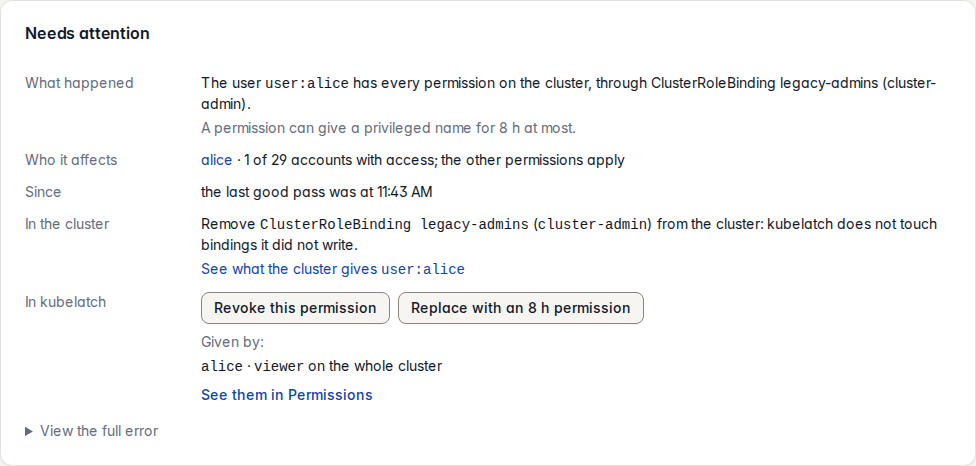
Each signal of the cluster is a block, the worst first, in the order of Needs attention in Clusters. A block has up to five rows:
- What happened: the problem, in the interface's language.
- Who it affects: the people, by login, and how many of the accounts with access that is (
alice · 1 of 29 accounts with access; the other permissions apply). - Since: when the last good pass was, while the cluster is blocked or kubelatch can't work on it.
- In the cluster: what only the cluster can fix, with the evidence.
- In kubelatch: what kubelatch can do.
In the cluster always comes before In kubelatch. Under the blocks, View the full error shows the English text of a cluster in error. What each problem says, and its fix, is in Reconciliation.
What to do with a privileged name
When the cluster gives privileged access to the name a person enters with, and a permission of theirs lasts more than 8 hours, the cluster says Blocked and that person can't use it through kubelatch (When the cluster gives privileged access to a name). The block offers three ways out, in this order:
- First, in the cluster. When a binding kubelatch didn't write gives the name its privilege, the block names it, such as
Remove ClusterRoleBinding legacy-admins (cluster-admin) from the cluster: kubelatch does not touch bindings it did not write., and See what the cluster givesuser:aliceopens it in What this cluster knows. Remove that binding with the cluster's administrator kubeconfig: from the next pass the name is no longer privileged and the person's permissions apply as they are. When the privilege comes from a privileged namespace, the block says what makes it so, and that is what to remove. A native role that gives privileged access does so by design: it's granted for 8 hours at most. - Then, in kubelatch, Revoke this permission, or Revoke these N, revokes the permissions that last too long, with the confirmation of Revoke several permissions. Choose it when that person shouldn't use the cluster through kubelatch. A group permission links to its group, and an agent session has Cut the session.
- Or, when the name is a person's, Replace with an 8 h permission revokes the permission and grants the same role, in the same place, for 8 hours. For those 8 hours the person enters with everything the cluster gives that name, not only what the role allows, and the confirmation says so before anything else:
For those 8 h, alice enters with what the cluster gives user:alice: has every permission on the cluster, through ClusterRoleBinding legacy-admins (cluster-admin).
If the revoke goes through and the new permission is refused, the block says so and Grant again opens the permission form with the account, the cluster, the namespace and the role filled in. The control plane records both changes, the revoke with its reason (Audit and retention). A group's privileged name only offers to revoke: replacing would give privileged access to every member at once.
The cluster's provider
Each cluster shows the platform it runs on: Amazon EKS, Google Kubernetes Engine, Azure Kubernetes Service, DigitalOcean Kubernetes, Red Hat OpenShift, K3s, RKE2, Scaleway Kapsule, Exoscale SKS, OVHcloud Managed Kubernetes, Aruba Managed Kubernetes, Talos Linux, kind or Kubernetes, the generic one. It is a label for people: it changes no permission and works the same in the Free and Pro editions. The diagram, the List and Details draw its mark, as KUBELATCH_PROVIDER_LOGOS sets, and its name in text. The Provider row of Details adds where it comes from: (detected), (set by hand) or, before the first reconciliation, (not detected yet).
Every reconciliation works it out, so clusters registered before this version have it after their next pass, without applying the bootstrap again. It looks, in this order, at:
- The API groups the cluster serves:
config.openshift.iomeans OpenShift. - The Kubernetes version read when the cluster was enrolled:
-eks-means Amazon EKS,-gke.Google Kubernetes Engine,+k3sK3s and+rke2RKE2. - The address of the API server, when it ends in
.eks.amazonaws.com(Amazon EKS),.azmk8s.io(Azure Kubernetes Service),.k8s.ondigitalocean.com(DigitalOcean Kubernetes),.api.k8s.<region>.scw.cloud(Scaleway Kapsule, infr-par,nl-amsandpl-waw),.sks-<zone>.exo.io(Exoscale SKS, in its seven zones) or.k8s.ovh.net(OVHcloud Managed Kubernetes).
With no signal it says Kubernetes. It never says kind, Talos Linux nor Aruba Managed Kubernetes: set those by hand. A cluster registered with kubelatch runs inside this cluster has the address https://kubernetes.default.svc, which tells nothing, so on Azure Kubernetes Service and DigitalOcean Kubernetes set the provider by hand. If the cluster does not answer the reading of its API groups, the pass keeps the value it had.
To set it by hand, click Edit in the Provider row of Details. The list starts with Automatic (…), the one worked out, and goes on with the nine providers; Save applies it at once, with no confirmation, and Automatic hands the choice back to kubelatch. What you set stays until you take it back, and the reconciliation keeps working out the other one, so Automatic (…) is always up to date. Each change is recorded as cluster.provider.update (Audit and retention); PATCH /api/clusters/<id> does the same.
Identity in the cluster
The Identity in the cluster card sets the name each person carries inside the cluster when kubelatch calls it: the Impersonate-User the proxy sends. The default, user:{login}, is kubelatch's own name (user:ana). A cluster whose own SSO already names people otherwise can use that name instead, so that the apiserver's audit log and the bindings to users name each person the same whichever way they come in. Why, and what it changes, is in kubelatch on top of the SSO you already have; which template fits each provider, in Cluster SSO by provider.
The template is free text around exactly one variable:
| Variable | What it is |
|---|---|
{login} |
The account's kubelatch login. |
{email} |
The verified e-mail of the account's identity at kubelatch's OIDC provider. |
{oidc_subject} |
The subject of that identity: the value of the claim OIDC_SUBJECT_CLAIM names. |
{github_login} |
The account's linked GitHub login. |
oidc:{email} names Ana oidc:ana@acme.com. The fixed text can't start with system:, nor hold spaces, control characters or stray braces, and a rendered name takes 253 characters at most. user: and bot: are kubelatch's own names, for people with the default template, AI agents and bots: only the default template starts with user:, and no template starts with bot: (400 cluster.template_reserved_prefix). {email} and {oidc_subject} need OIDC login to be configured: without it nobody has them, and saving answers 409 cluster.template_needs_oidc. The e-mail an administrator types in Users never counts: only the one the provider vouched for. Bots always enter as bot:<name>.
With domain access or join requests, logins go first come, first served across every allowed domain: bob@contractor.io may get the login bob that the cluster's bindings meant for bob@acme.com. On a cluster that binds users by name, choose {email} or {oidc_subject} then.
To change it, click Edit, type the template in How each person enters (Impersonate-User), and click Save. The preview below follows what you type. If the new template leaves people out or makes two accounts share a name, Save a template that leaves people out says how many and asks first; Save anyway saves it, since the step in between is sometimes unavoidable.
On saving, kubelatch records a cluster.identity.update with the template before and after (Audit and retention) and reconciles the cluster at once. From then on the proxy sends the new names, and streams opened under an old name (exec, port-forward, watch) are cut within seconds; until the reconciliation ends, a request may get the apiserver's 403. A change of the person's e-mail at the provider, or of their GitHub login, changes their name on the cluster the same way.
The preview
Preview with everyone who has permissions here renders the template, or the draft while you edit it, for every person with an active permission on the cluster:
- The name each person will enter with.
- For whoever lacks what the template needs, a pill, no verified e-mail, no SSO identity or no linked GitHub account, with what it means: 403 until they link their SSO. invalid name marks an account whose data gives no valid name, such as an e-mail that would start with
system:. - Under Two accounts would enter with the same name, in red, the accounts that would share a name.
- The privileged pill beside a name to which the cluster gives privileged access. If the cluster can't be read, the preview says so and shows no such pill.
Accounts that can't be named
A person whose account lacks the fact the template needs can't use that cluster through kubelatch. Their requests get a 403 that says why, such as this cluster identifies people by their verified e-mail and the account `carol` has none: sign in with the identity provider, or ask an administrator to link it. This is a warning, not an error: the cluster stays Ready, everyone else keeps working, and each reconciliation records the accounts it couldn't name on the cluster. The cluster's page says Warning in its header and lists them in Needs attention, with Go to Identity in the cluster; the Identity in the cluster card opens with a note that lists them, and its preview shows them first, with why for each; in Clusters, the cluster says Warning and Needs attention names it with the warnings.
For {email} and {oidc_subject}, the person signs in once with the OIDC provider, which links their identity (How accounts are linked), or you send them a linking link from Users. For {github_login}, they link GitHub (GitHub login). Their other clusters are not affected.
Names that clash
Two enabled accounts that render the same name, such as ana and ana.acme.com with the same verified e-mail, can't both enter: the reconciliation leaves the name out of what the proxy may impersonate, both get the apiserver's 403, and the cluster goes to Error with identity: logins ana and ana.acme.com both render `oidc:ana@acme.com`. A new permission that would make such a clash is refused with 409 grant.identity_collision. Change the template, or disable one of the accounts. The apiserver tells the people apart anyway: Impersonate-Uid always carries the account's own identifier.
When the cluster gives privileged access to a name
With a template, the name kubelatch sends may be one the cluster already gives access to: a person the cluster knows as oidc:ana@acme.com, with a ClusterRoleBinding to edit, creates workloads in every namespace through kubelatch with any permission there, even viewer. So when the cluster gives that name privileged access, every permission of that person on that cluster needs an expiry of 8 hours at most, whatever its role. With any template other than the default, granting reads the cluster's RBAC live, and refuses the permission when the cluster can't be read. Each reconciliation reads it again, leaves out a name with a permission that breaks the rule, and says so: privileged: the user `oidc:ana@acme.com` gets workloads in every namespace through ClusterRoleBinding ops-edit (edit) and the grant of ana has no 8 h expiry. The cluster's page names the permissions behind it and what to do, in the cluster first (What to do with a privileged name), and Permissions marks them. An AI agent the person delegates to never carries that name: it enters as user:<login> (AI agents).
What this cluster knows
The What this cluster knows card lists the subjects of the cluster's RoleBindings and ClusterRoleBindings, in two tables, Groups and Users, each with what it is Bound to: the roles, on the whole cluster or in which namespaces. A name to which the cluster gives privileged access carries the privileged pill, with a line under it for each reason: what it can do, where, and through which binding and role. A name that starts with system: says forbidden for native roles. kubelatch's own names fold into one line (and 3 kubelatch names), and ServiceAccounts aren't listed.
Under the tables, Privileged namespaces lists the privileged namespaces: the protected ones, and each of the others with the ServiceAccount that makes it so. When the cluster gives privileged access to everyone it authenticates, or to every pod, the card opens with a note that says so: kubelatch can't limit that.
Use it to pick the template above and the groups of a native role without typing them. kubelatch keeps the read for five minutes (Read 2 min ago.); Read again reads the cluster at once. Each list stops at 500 names. Reading needs no new permission: the reconciler's ServiceAccount could already read the cluster's RBAC.
Reconciliation
The reconciler keeps each tier's ClusterRoles, the ClusterRoles of the custom roles in use, one binding per role and scope with active permissions, and the exact list of users and groups the proxy can impersonate, in sync on the cluster. kubelatch-proxy starts out only allowed to impersonate uids; the reconciler adds users and groups to it as permissions exist: the names the cluster's identity template renders, and the groups of the native roles with active permissions, for which it writes no binding. Each pass also reads the cluster's ClusterRoles, ClusterRoleBindings, Roles and RoleBindings, its own and those it didn't write, to apply the 8-hour rule of privileged access, and lists its namespaces, to check each permission's namespace again: it must still exist and, for the roles that require it, still enforce Pod Security (the rules). It runs on each cluster:
- On any change: granting or revoking a permission, saving tokens, disabling or re-enabling an account, changing the identity template, or a change of someone's identity at the OIDC provider or on GitHub. Usually takes under a second.
- When a namespace with permissions changes its
pod-security.kubernetes.io/enforcelabel, is deleted or is created again: within seconds, right after the pass in progress. kubelatch watches each cluster's namespaces to notice; if it can't watch them (the log saysnamespace watch down), the 10-minute pass covers it. While namespaces with permissions keep changing on a cluster (a label that flips, namespaces that come and go), kubelatch reconciles it at least every 30 seconds rather than at every change, so a change there can wait up to 30 seconds. - Every 10 minutes. This pass removes bindings for permissions that have expired (the proxy stops accepting them the instant they expire).
- On demand: Reconcile in the cluster's page or in the menu of its card or row in Clusters, or
POST /api/clusters/<id>/reconcile.
The manual call responds 200 with the cluster, 502 with the number of problems if the cluster fails, and 409 if another pass is already running or the cluster is still Not enrolled.
If a pass fails, the cluster moves to Error, or to the level its problem calls for (Blocked, Unreachable…), and Needs attention, on the Status tab of its page, says each problem in the interface's language, with its fix, and View the full error gives the English text. In Clusters, Needs attention says its first problem and links to them.
- A privileged name kept for more than 8 hours, or given by a group permission (the 8-hour rule): the block says how the cluster gives the name privileged access, lists what gives it for longer (permissions, group permissions, agent sessions) and who it leaves without access. Fix it in the cluster first, then in kubelatch: What to do with a privileged name. See them in Permissions lists the permissions there.
- A namespace that no longer enforces Pod Security: a
developer,debugger,adminor custom role that requires it, in a namespace whosepod-security.kubernetes.io/enforcelabel is no longerbaselineorrestricted, stops taking effect on the next pass, and the people who have it keep the rest of their access. The block gives the command to set the label again, with a copy button, and lists the permissions with no effect, with Revoke these N and their group's link. Once the label is back, they take effect again on the next pass, with nothing to do in kubelatch. If the namespace needsprivileged, for a node agent for example, revoke the permissions instead. Native roles aren't checked: the cluster's own RBAC decides what their groups can do. - A namespace that no longer exists: its permissions stop taking effect. Revoke them, or they take effect again if the namespace comes back.
- In both cases, when a binding kubelatch didn't write also gives kubelatch's group of that role and namespace, or kubelatch couldn't delete its own binding, the people with that permission lose access to the whole cluster until it's fixed, and the block says how many.
- Two accounts with one name (Names that clash): change the identity template or disable one of them.
- An incomplete or previous bootstrap: Re-enroll without changing the tokens opens the steps to apply the current manifest with the same tokens (Update the bootstrap).
- A custom role that no longer passes validation: edit or delete the role it links to.
- An invalid identity template: Go to Identity in the cluster and set it again.
- An object the cluster refused: the block names it and what the cluster answered.
- The reconciler's token can't be decrypted, or the cluster refuses it (Token rejected): Re-enroll, in the block or in the page's menu, with new tokens.
kubelatch retries with growing backoff: 1, 2, 4… minutes, up to 10. A namespace that loses Pod Security or is deleted while permissions are still active leaves the cluster in Error until it's fixed or they're revoked, but the rest of the bindings keep being applied. So do the names two accounts share, the names left out by the cluster-admin rule (Identity in the cluster), and native roles granted on a cluster with the previous bootstrap (native roles are granted on this cluster but it has the previous bootstrap: apply the bootstrap manifest again). A pass that can't read the cluster keeps the permissions it had found with no effect until the next one that can. The mechanism's details are in Architecture.
Everything kubelatch creates carries the labels app.kubernetes.io/managed-by=kubelatch and kubelatch.io/instance=<KUBELATCH_INSTANCE_ID>. It only deletes bindings with those labels and its own names, and never deletes anything after a read error. To add CRDs to a tier, see Grant permissions.
Update the bootstrap
The bootstrap manifest kubelatch generates bounds the reconciler with the kubelatch-reconciler-jail admission policy, instead of the fixed list of names the previous manifest gave it (Security model). A cluster registered with the previous manifest keeps working with the system tiers; custom roles need the new one.
Such a cluster says Bootstrap v1: custom roles cannot be granted on this cluster. in Needs attention, on the Status tab of its page. To update it:
- Click Re-enroll without changing the tokens, in that block (the menu of the page has it too). The card, titled Re-enroll "
" without changing the tokens , opens the steps above the tabs, works like the registration ones and says the command applies the current manifest and sends the same tokens: fill in kubectl context (optional) if you like and click Generate command. - Run the command with that cluster's administrator kubeconfig. It applies the current manifest and sends kubelatch the same tokens, so nothing that uses them stops working, and the reconciliation starts at once. The card says Re-enrolled, tokens unchanged. Reconciliation under way.
By hand, under Do it by hand in the same card: download the manifest (download bootstrap.yaml) and apply it with that cluster's administrator kubeconfig:
kubectl --kubeconfig <cluster-kubeconfig> apply -f kubelatch-bootstrap-<id>.yaml
The tokens don't change and there's nothing to paste. kubelatch notices on the next reconciliation, at most 10 minutes later. Click Reconcile on the page right after applying: the manifest returns kubelatch-proxy to the uids-only rule, as when rotating tokens, and the proxy can't impersonate anyone on that cluster until a reconciliation restores the list.
On a cluster that already has the current manifest, when a release's notes say the manifest changed, choose Re-enroll without changing the tokens in the page's menu: generate the command, or download the manifest under Do it by hand, apply it and click Reconcile as above.
The policy comes first in the manifest, so kubectl creates it before it widens the reconciler's ClusterRole and the new rights aren't granted before the policy exists. The API server starts enforcing a new policy a few seconds after it's created. If someone deletes the policy or its binding afterwards, or weakens them (a binding that only warns, for instance), the cluster goes to Error with bootstrap incomplete and kubelatch writes no custom role there until the manifest is applied again. If the binding was edited, delete the kubelatch-reconciler-jail ValidatingAdmissionPolicyBinding first: the manifest is applied client-side and doesn't remove a matchResources or paramRef added out of band. It doesn't delete the custom roles already on the cluster either.
If you applied the hardening policy, the update goes through: the manifest doesn't change the kubelatch-proxy and kubelatch-reconciler ClusterRoleBindings.
Rotate the ServiceAccount tokens
The tokens live in the cluster's kubelatch-proxy-token and kubelatch-reconciler-token Secrets. To change them, open the cluster's page in Clusters, open its menu and choose Re-enroll. The card, titled Re-enroll "--rotate baked in. Run it with the cluster's administrator kubeconfig, as when registering. It:
- Deletes both Secrets: the old tokens stop working and the proxy fails on that cluster until the command finishes.
- Applies the manifest again, so Kubernetes creates new tokens.
- Sends the new tokens to kubelatch, which saves them and starts a reconciliation.
Applying the manifest again returns kubelatch-proxy to the uids-only rule: the proxy can't impersonate anyone until the next reconciliation. Saving the tokens already kicks off a reconciliation that restores the list (the card says Re-enrolled with new tokens. Reconciliation under way.); Reconcile is only there to confirm the cluster goes back to Ready.
The card describes the command it shows. If you ask the menu for the other re-enrollment while a command is out, a line says what the command shown does (The command shown keeps the tokens… or The command shown gets new tokens…); to get the other one, Invalidate it and generate another. When a link generated elsewhere (another tab, another administrator) runs on an enrolled cluster, the card only says Re-enrolled. Reconciliation under way.: it can't know whether that command changed the tokens. Cancel closes the steps if no command is out.
You can also rotate by hand: delete the two Secrets with kubectl --kubeconfig <cluster-kubeconfig> -n kubelatch-system delete secret kubelatch-proxy-token kubelatch-reconciler-token, apply the manifest and paste the JSON from Do it by hand in the same card.
Harden the cluster (optional)
A namespace admin, whether granted by kubelatch or native, can create a RoleBinding to kubelatch-developer for anyone. That doesn't grant access through kubelatch, but a subject with a native credential would gain that role natively, and the binding also confuses the reconciler.
The policy is files/vap-kubelatch-bindings.yaml in the Helm chart: a ValidatingAdmissionPolicy (Kubernetes 1.30 or later). It only lets kubelatch-system/kubelatch-reconciler create or change bindings to a ClusterRole whose name starts with kubelatch-. Namespaced Roles stay free, whatever their name: kubelatch never binds one, and the chart's CloudNativePG database has its own. Apply it on each managed cluster, with its kubeconfig, from the chart of the version you run (KUBELATCH_VERSION, as in Install):
helm pull oci://ghcr.io/picaportelabs/charts/kubelatch --version "$KUBELATCH_VERSION" --untar
kubectl --kubeconfig <cluster-kubeconfig> apply -f kubelatch/files/vap-kubelatch-bindings.yaml
If the management cluster is registered in kubelatch too, the chart installs the policy there with hardening.enabled: true in your values and a helm upgrade.
Apply it after the bootstrap. From then on, a binding created by hand to a kubelatch-* ClusterRole is denied, and the reconciler keeps working. A cluster with the policy of 0.59.0 or earlier needs the current one.
The policy also blocks the bootstrap itself. Its kubelatch-proxy and kubelatch-reconciler ClusterRoleBindings point at kubelatch-* ClusterRoles, and whoever applies the bootstrap is an administrator, not the reconciler. Re-enroll works because those bindings don't change. But a bootstrap that has to create or change them fails with Forbidden:
- moving the cluster to another instance (it changes its
kubelatch.io/instancelabel); - registering it again after removing the bootstrap.
In those cases, remove the policy's binding first, apply the bootstrap, then reapply the policy:
kubectl --kubeconfig <cluster-kubeconfig> delete validatingadmissionpolicybinding kubelatch-bindings
kubectl --kubeconfig <cluster-kubeconfig> apply -f kubelatch-bootstrap-<id>.yaml
kubectl --kubeconfig <cluster-kubeconfig> apply -f kubelatch/files/vap-kubelatch-bindings.yaml
In the management cluster with hardening.enabled, the last step is helm upgrade with the same values, which creates the binding again.
Delete a cluster
In Clusters, open the menu on the cluster's card or row, or on its page, choose Delete and confirm (or DELETE /api/clusters/<id>). kubelatch:
- Tries to clean up the cluster's RBAC with the reconciler's token, for up to 15 s. It deletes this instance's bindings, its tier ClusterRoles and its custom roles' ClusterRoles (
kubelatch-role-<id>), and leaveskubelatch-proxywith theuids-only rule. - Deletes the cluster, its permissions and the credentials scoped to it. Audit rows are kept.
When the cleanup went well, Clusters says so in a notice (Cluster "<id>" deleted; its RBAC was removed from the cluster.). Otherwise a final dialog, Cluster
If the cleanup didn't happen, remove what's left with the cluster's kubeconfig. This doesn't touch the bootstrap:
kubectl --kubeconfig <cluster-kubeconfig> delete clusterroles,clusterrolebindings -l 'app.kubernetes.io/managed-by=kubelatch,kubelatch.io/kind in (binding,tier,role)'
kubectl --kubeconfig <cluster-kubeconfig> delete rolebindings -A -l 'app.kubernetes.io/managed-by=kubelatch,kubelatch.io/kind in (binding,tier,role)'
With several kubelatch instances, add ,kubelatch.io/instance=<id> to the selector.
Remove the bootstrap too
Deleting the cluster doesn't delete the kubelatch-system namespace, the ServiceAccounts or the reconciler's ClusterRole, which keeps its permissions. To fully decommission it:
kubectl --kubeconfig <cluster-kubeconfig> delete namespace kubelatch-system
kubectl --kubeconfig <cluster-kubeconfig> delete clusterroles,clusterrolebindings kubelatch-proxy kubelatch-reconciler
kubectl --kubeconfig <cluster-kubeconfig> delete validatingadmissionpolicybinding,validatingadmissionpolicy kubelatch-reconciler-jail
Delete the kubelatch-reconciler-jail policy last, once the reconciler's ClusterRole is gone.
If you applied the hardening policy, delete it too (it doesn't carry kubelatch's labels):
kubectl --kubeconfig <cluster-kubeconfig> delete validatingadmissionpolicybinding,validatingadmissionpolicy kubelatch-bindings
Move a cluster to another instance
A cluster is registered on a single kubelatch instance. The KUBELATCH_INSTANCE_ID label makes each instance only touch its own objects. To move it:
- If you applied the hardening policy, remove its binding: the new bootstrap changes its ClusterRoleBindings' label.
- Register it on the new instance.
- Delete it on the old one. The cleanup only removes bindings and ClusterRoles labeled with the old instance, but it does return
kubelatch-proxyto theuids-only rule. - Click Reconcile on the new instance right after.
This doesn't work for sharing a cluster between two instances at once, because the bootstrap is a single set per cluster.